Follow on Twitter using the following hashtags or usernames: #NFD41
Watch on YouTube
Watch on Vimeo
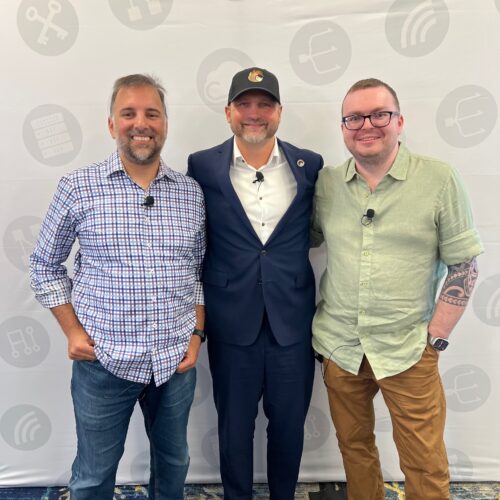
Hedgehog explained how the shift from AI training to inference is reshaping the data center network. Marc Austin, Manish Vachharajani, and Sergei Lukianov covered disaggregated inference, which splits prefill and decode across different accelerators, the role of KV cache transfers over a scale-out RDMA Ethernet fabric, and multi-plane back-end designs that keep online inference clusters available. The session took place at Networking Field Day 41, with Austin, Hedgehog’s founder and CEO, setting up the business case before handing off to Vachharajani, the company’s CTO.
Austin framed the session around goodput, meaning time to first token and token throughput, and pointed to a Computex demonstration by customer SambaNova in which a sample workload took 90 seconds on an NVIDIA B200 alone but 30 seconds when paired with an air-cooled SambaNova SN40 RDU over a Hedgehog AI network. Vachharajani explained why: prefill is compute-bound, decode is limited by memory bandwidth, and a single model-in-a-box layout cannot optimize for both. Splitting them across separate pools, however, means shipping the KV cache from prefill to decode. At roughly 320 KB per token for Llama 3, a 32K-token prompt produces about 10 GB, and that transfer sits directly on the user’s response path, taking about 860 milliseconds at 100 Gbps, 215 milliseconds at 400 Gbps, and 100 milliseconds at 800 Gbps per GPU.
The result, Vachharajani argued, is that inference now needs the full scale-out RDMA back-end network once reserved for training, plus a KV cache storage tier, and unlike training it must stay online around the clock. Faster B300 NICs with 800 Gbps breakouts push designs toward multi-plane fabrics, two disconnected Clos networks that libraries such as UCX and NIXL can route across, so an entire plane can be taken offline for maintenance at reduced performance. Hedgehog is designing a successor cluster that adds a converged tier connecting both planes to storage and accelerators that cannot handle multi-plane networking, a topology outside standard reference architectures. Because pairing GPUs with decode accelerators from SambaNova, Groq, or Cerebras requires an interoperable interconnect, Vachharajani said that interconnect today is Ethernet with RoCE, which puts the network at the center of disaggregated inference.
Personnel: Manish Vachharajani, Marc Austin
Watch on YouTube
Watch on Vimeo
Hedgehog demonstrated disaggregated inference running across a pair of NVIDIA DGX Spark systems on a Hedgehog AI network and walked through the software stack behind it. Sergei Lukianov, Manish Vachharajani, and Marc Austin also explained how Hedgehog’s Kubernetes-based control plane handles GitOps, tenant-aware observability, EVPN multi-tenancy, multi-fabric interconnects, and fabric bring-up for AI clusters. The session took place at Networking Field Day 41, with Lukianov, Hedgehog’s co-founder and chief architect, leading the demo before Vachharajani and Austin joined him for an extended delegate Q&A.
Lukianov described a stack built on NVIDIA Dynamo for orchestration, vLLM for both prefill and decode, and NIXL over UCX for KV cache transfer, noting that these libraries know little about network topology and expect the fabric to simply work. The demo ran on DGX Sparks, which present the same software environment as B200 servers, attached to Celestica DS5000 Tomahawk 5 switches in Hedgehog’s Fremont lab and running RoCE over an EVPN fabric with host-side BGP for multi-homing. In aggregated mode, almost no traffic crossed between the nodes; once disaggregated, a few gigabits per second of KV cache moved from one Spark to the other, all of it RoCE, which Lukianov said would reach hundreds of gigabits at data center scale. He then showed Hedgehog’s Kubernetes CRD-based API, with VPC objects managed through Argo CD and telemetry enriched with tenant information for Prometheus and Grafana.
In the Q&A, the presenters positioned Hedgehog as a way to extend NVIDIA reference architectures to mixed-vendor accelerators and topologies such as the converged tier, while running EVPN on the back end so any tenant placed in a VPC is isolated automatically. Vachharajani described a gateway that applies ACLs and NAT between VPCs, including the internet, in roughly 20 lines of configuration, and Lukianov previewed a feature arriving the following week for interconnecting separate fabrics with full tenant isolation. Hedgehog ships as an appliance ISO, with a switch agent pulling declarative configuration much as a kubelet pulls pods, and supports Broadcom Enterprise SONiC and Cumulus. An OCP-accepted reference architecture and cabling validation for deployments of roughly 60,000 connections reflect the company’s larger goal of making AI fabric operations accessible to DevOps engineers rather than only networking specialists.
Personnel: Manish Vachharajani, Sergei Lukianov
Thank you for being part of the Tech Field Day community! Our mailing list is a great way to stay up to date on our events and technical content, and we appreciate your signup.
We promise that we’ll never spam you, send ads, or sell your information. This list will only be used to communicate with our community about our events and content. And we’ll limit it to no more than one message per week.
Although we only need your email address, it would be nice if you provided a little more information to help us get to know you better!